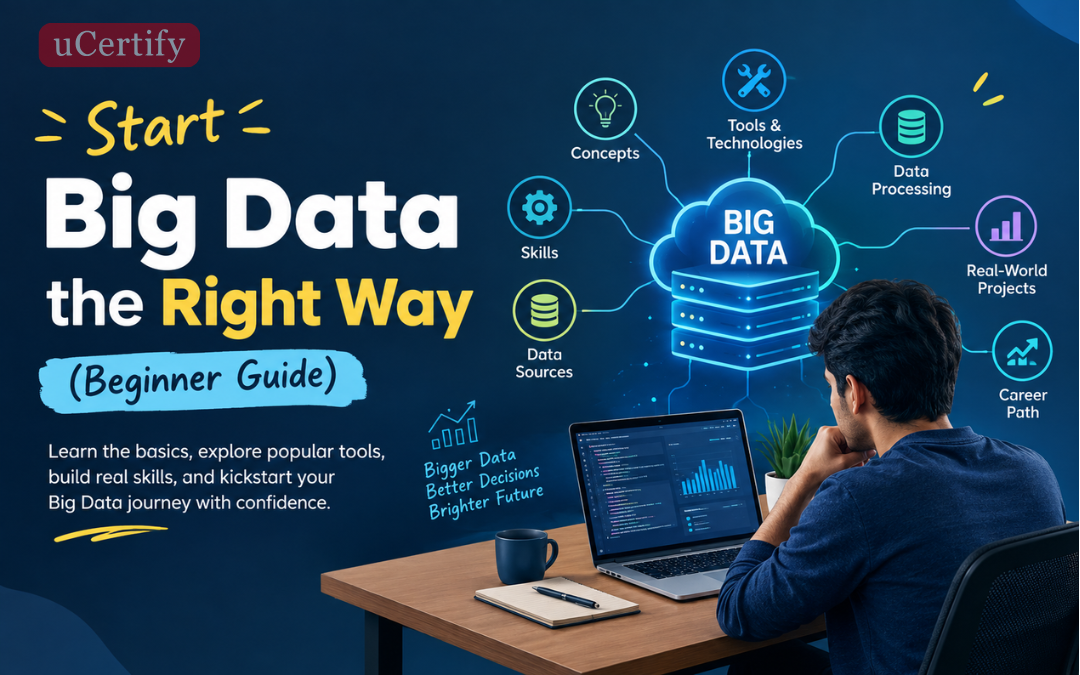
Every search, purchase, video stream, app interaction, online payment, and GPS request leaves behind data. This guide will help you Start Big Data the Right Way.
Now imagine those actions happening millions of times a minute.
That is the kind of problem that leads organizations to Big Data.
But here is where beginners often get stuck. They see names such as Hadoop, Spark, Kafka, NoSQL, data lakes, warehouses, and cloud platforms and assume they need to learn all of them before they can even get started.
You don’t.
The better starting point is to understand why Big Data systems exist in the first place.
Once that makes sense, the tools become easier to place. You can look at Spark and understand the processing problem it addresses. You can look at Kafka and understand why streaming events might need a dedicated system. You can look at cloud storage and understand why keeping huge datasets on a single machine is not always practical.
To Start Big Data the Right Way, it’s essential to grasp the foundational concepts.
This Big Data beginner guide takes that approach. Instead of starting with a list of technologies, we’ll first understand the problem, then the architecture, then the skills and tools that help solve it to Start Big Data the Right Way.
What You’ll Be Able to Decide After Reading This Guide
By the end of this guide, you should be able to:
- Explain what Big Data means and why size alone does not define it.
- Understand the 5 Vs of Big Data.
- Explain why distributed computing becomes useful at scale.
- Distinguish data storage, processing, streaming, and analytics.
- Understand where technologies such as Hadoop, Spark, Kafka, and NoSQL fit.
- Identify the SQL and Python skills worth learning first.
- Understand how cloud platforms fit into modern data architectures.
- Choose a practical starting point for learning Big Data.
- Design a small project that demonstrates Big Data concepts rather than simply collecting a large dataset.
What Is Big Data?
Big Data describes data environments where the amount, speed, variety, complexity, or reliability requirements of information create challenges that conventional approaches may struggle to handle efficiently.
Notice something important here: there is no single number that suddenly turns ordinary data into Big Data.
A 1-terabyte dataset may be difficult for one organization and completely manageable for another. The technology, infrastructure, workload, processing requirements, and response time all matter.
Consider an online shopping platform.
Every day, it may generate information from:
- Product searches
- Customer accounts
- Website clicks
- Orders
- Payments
- Product reviews
- Delivery locations
- Mobile applications
- Customer-support interactions
- Inventory systems
Now imagine that information arriving continuously from millions of users.
The problem isn’t just storing the information. The company may also need to process it quickly, combine different types of data, detect unusual activity, understand customer behavior, and make information available to other systems.
That is where Big Data engineering becomes interesting.
The 5 Vs of Big Data
The 5 Vs are a useful way to understand the different challenges that can appear when organizations work with large-scale data.
Instead of memorizing them, imagine that we’re following the data generated by our online shopping platform.
1. Volume
Volume refers to the amount of data.
A small website may generate a manageable number of records each day. A global platform could produce terabytes or more across databases, logs, images, transactions, and application events.
As the amount grows, storing and processing everything efficiently becomes an engineering problem.
The important question isn’t simply:
“How many gigabytes do we have?”
It is:
“Can our current system store, process, and query this data within the time and cost requirements of the business?”
2. Velocity
Velocity describes how quickly data is generated and how quickly it needs to be processed.
Imagine a customer clicking:
Product viewed → product added to cart → payment completed
Those events can happen continuously.
Some applications can process information later in a scheduled batch. Others need events to be handled almost immediately.
For example, a fraud-detection system may need to examine a transaction while it is happening rather than waiting until the end of the day.
That difference introduces the idea of stream processing.
3. Variety
Not every piece of data arrives as a neat database table.
An organization may have:
- Transaction records
- JSON events
- Images
- Videos
- Audio
- Sensor readings
- Application logs
- Social-media data
- Customer messages
- Database records
This is a variety.
The challenge is not simply keeping all these files somewhere. Systems need ways to ingest, organize, transform, and use data that may have very different structures.
4. Veracity
Veracity concerns the reliability and quality of data.
Suppose our shopping platform receives two customer records for the same person, an incorrect delivery address, and a transaction with missing information.
The system now has plenty of data—but some of it cannot be trusted without additional processing.
Data quality problems can include:
- Duplicate records
- Missing values
- Incorrect formats
- Conflicting information
- Invalid values
- Outdated records
Large-scale systems do not remove the need for data quality. In many cases, they make the problem harder.
5. Value
The fifth V is Value.
This is the part that often gets overlooked.
A company does not build a Big Data environment simply because it wants to collect more information.
It wants useful results.
For example:
- Which products are gaining demand?
- Why are customers abandoning their carts?
- Which transactions need further investigation?
- Which machines are showing warning signs?
- Which delivery routes are becoming inefficient?
The data becomes valuable when it can support an action, decision, prediction, or useful analysis.
When Does Data Become a Big Data Problem?
This is one of the most useful questions for a beginner.
Suppose you have a 20 GB dataset.
If your laptop can process it comfortably, there may be no reason to introduce a distributed processing system just because the dataset sounds large.
Now imagine the workload involves:
- Several terabytes of data
- Continuous incoming events
- Multiple data formats
- Processing across many machines
- Strict response-time requirements
- High availability requirements
The problem has changed.
So don’t use dataset size alone as your definition of Big Data.
A better way to think about it is:
Big Data problems appear when the scale or complexity of a workload pushes beyond what a conventional setup can handle efficiently.
That shift in thinking is more valuable than memorizing a particular storage threshold.
Big Data vs. Traditional Data Systems
Big Data does not mean that traditional databases have become useless.
Relational databases remain extremely important.
If a small application needs to store customer accounts and transactions, a traditional relational database may be exactly what it needs.
The challenge appears when the workload grows in scale, speed, variety, or processing complexity.
This is where distributed computing becomes important.
What Is Distributed Computing?
Instead of asking one computer to handle the entire workload, a distributed system can divide work across multiple machines.
Think about moving a house.
One person can carry every box, but the job becomes easier when several people divide the work.
A distributed data system applies a similar idea:
Large Dataset
↓
Split the Work
↓
┌─────────┬─────────┬─────────┐
│ Machine │ Machine │ Machine │
│ 1 │ 2 │ 3 │
└─────────┴─────────┴─────────┘
↓
Combine Results
↓
Final Output
The machines work as a group.
This introduces several important concepts you’ll eventually encounter:
- Nodes
- Clusters
- Parallel processing
- Distributed storage
- Fault tolerance
- Data partitioning
You don’t need to master all of them on your first day. You do need to understand why they exist.
How Does a Big Data System Work?
A simple Big Data workflow can look like this:
Data Sources → Ingestion → Storage → Processing → Analytics → Action
Let’s use our online shopping example.
1. Data Sources
Data can originate from websites, mobile applications, databases, payment systems, sensors, APIs, and internal business applications.
For example:
A customer searches for a laptop.
That interaction creates an event.
2. Data Ingestion
The event needs to move into the data environment.
Some data arrives in batches. Other data arrives continuously.
For streaming workloads, technologies such as Apache Kafka can be used to move and distribute event streams.
Think of Kafka as part of the event-delivery layer rather than as the entire Big Data system.
3. Data Storage
The incoming information needs somewhere to be stored.
Depending on the workload, organizations may use:
- Databases
- Object storage
- Distributed file systems
- Data warehouses
- Data lakes
- Lakehouse-style architectures
The storage choice depends on how the information will be used.
4. Data Processing
Raw data often isn’t ready for analysis.
It may need to be:
- Cleaned
- Validated
- Joined
- Transformed
- Aggregated
- Enriched
A distributed processing engine such as Apache Spark can be used for large-scale processing workloads.
5. Analytics
Once the data has been prepared, analysts, engineers, and data scientists can work with it.
They may investigate:
- Sales patterns
- Customer behavior
- Product performance
- Operational problems
- Anomalies
- Forecasting questions
6. Action
The final result should lead somewhere.
A dashboard may help a manager understand sales.
A recommendation system may use customer behavior.
An alerting system may flag an unusual transaction.
A machine-learning system may use processed data to generate predictions.
That is the complete idea:
Data enters the system, gets processed, becomes information, and eventually supports an action.
A Simple Big Data Architecture Example
Let’s make the idea more concrete.
Imagine an online store receiving thousands of customer events.
A simplified architecture could look like this:
Website / Mobile App
↓
Events
↓
Kafka
↓
┌──────┴──────┐
↓ ↓
Real-Time Storage
Processing Layer
↓ ↓
Alerts Data Lake
↓
Spark
↓
Processed Data
↓
Warehouse / Analytics
↓
Dashboard
This is not the only possible architecture.
That’s important.
Real systems vary depending on business requirements, cost, data volume, latency, security, and existing infrastructure.
The purpose of the diagram is simply to show that Big Data is an ecosystem of connected components, not one giant application.
Big Data Technologies Beginners Should Know
Now that the architecture makes sense, the technology names become easier to understand.
The question should not be:
“Which Big Data tool is the best?”
Instead ask:
“What problem does this technology solve?”
Apache Hadoop
Hadoop is a major part of Big Data’s history and introduced important concepts around distributed storage and processing.
You may encounter:
- HDFS
- YARN
- MapReduce
You do not need to master every Hadoop component before moving forward.
For a beginner, its biggest educational value is understanding the ideas behind distributed data systems.
Apache Spark
Apache Spark is a widely used engine for large-scale data processing.
It can support workloads involving:
- Batch processing
- Data transformation
- Analytics
- Streaming
- Machine learning workloads
When learning Spark, don’t focus only on syntax.
Ask:
What happens when this workload is divided across a cluster?
That question will teach you more than memorizing commands.
Apache Kafka
Apache Kafka is commonly used for event streaming.
Imagine an application continuously generating events:
User logged in
↓
Product viewed
↓
Item added to cart
↓
Payment completed
↓
Order shipped
A streaming system can help applications publish, transport, and consume those events.
That makes Kafka relevant when the timing of data matters.
NoSQL Databases
Relational databases organize data using tables and relationships.
NoSQL databases provide other data models and are often used when applications have particular scalability, availability, or data-model requirements.
Examples include:
- MongoDB
- Cassandra
- Redis
These technologies are not interchangeable.
A useful beginner question is:
What data model and workload does this database suit?
That’s more valuable than memorizing database names.
Don’t Skip SQL
Here’s an important point for anyone starting Big Data:
SQL still matters.
You will encounter SQL in many parts of the modern data ecosystem.
Start with:
- SELECT
- WHERE
- GROUP BY
- ORDER BY
- JOIN
- Aggregations
- Subqueries
- Common table expressions
- Window functions
You don’t need to become a database administrator.
But you should be comfortable asking questions of data.
For example:
Which products generated the most revenue last month?
That is a data question.
SQL gives you one practical way to answer it.
Learn Python Alongside Big Data
Python is another useful skill for beginners.
You can use it for:
- Data cleaning
- Analysis
- Automation
- API interaction
- Data pipelines
- Machine learning
- Working with distributed-data tools
Start with the fundamentals:
- Variables and data types
- Conditions
- Loops
- Functions
- Lists and dictionaries
- File handling
- Exception handling
- Modules and packages
Then start using Python on actual datasets.
For example, instead of completing ten unrelated programming exercises, write a small program that reads a CSV file, cleans missing values, calculates statistics, and saves the result.
That connects programming to data work.
Big Data and Cloud Computing
Modern data architectures increasingly make use of cloud infrastructure.
Cloud platforms can provide services for:
- Storage
- Databases
- Data warehouses
- Data lakes
- Data processing
- Streaming
- Analytics
- Machine learning
One reason cloud platforms are useful is that organizations can provision infrastructure without building every piece of physical hardware themselves.
For a beginner, don’t try to learn several cloud platforms simultaneously.
Choose one environment.
Learn:
Storage → Database → Compute → Analytics
Then build something.
The goal isn’t to memorize dozens of service names. You should understand how the pieces work together.
Big Data vs. Data Analytics vs. Data Science vs. Data Engineering
These areas overlap, which is why beginners often confuse them.
| Area | Main Focus |
| Big Data | Working with data environments where scale, speed, variety, or complexity creates engineering challenges |
| Data Engineering | Building pipelines and systems that collect, transform, store, and deliver data |
| Data Analytics | Examining data to understand patterns, trends, and business questions |
| Data Science | Using statistics, programming, experiments, and models to investigate problems and make predictions |
Here’s a simple example.
A company receives millions of customer events.
The data engineer builds the pipeline.
The data platform stores and processes the information.
The data analyst investigates sales patterns.
The data scientist might develop a model using the processed data.
The boundaries can vary between organizations, but the example shows how the roles can connect.
A Practical Big Data Learning Path
Don’t approach Big Data as one enormous subject.
Build your knowledge in layers.
Step 1: Learn Data Fundamentals
Start with:
- Databases
- Tables and records
- Primary and foreign keys
- Structured and unstructured data
- Basic data modeling
- SQL
At this stage, your goal is to become comfortable with data itself.
Step 2: Learn Python
Use Python to work with files, APIs, datasets, and simple automation.
Don’t wait until you know advanced Python.
Learn something, then use it immediately.
Step 3: Understand Distributed Systems
This is the point where your learning becomes more specifically related to Big Data.
Understand:
- Nodes
- Clusters
- Parallel processing
- Data partitioning
- Distributed storage
- Fault tolerance
You should be able to explain why a workload might need multiple machines.
Step 4: Explore Spark
Once distributed processing makes sense, start learning Spark.
Work with a dataset and compare how a task is handled locally versus through distributed processing concepts.
The purpose isn’t simply to learn Spark syntax.
It’s to understand the architecture behind the computation.
Step 5: Learn Streaming
Move into:
- Events
- Producers
- Consumers
- Topics
- Partitions
- Event processing
- Real-time pipelines
Kafka is one technology you can use to explore these concepts.
Step 6: Learn One Cloud Environment
Choose one cloud platform.
Learn its basic services for:
- Storage
- Compute
- Databases
- Analytics
Build a small project rather than collecting cloud-service definitions.
Step 7: Build Projects
This is where everything starts connecting.
A project forces you to make decisions.
Where does the data come from?
How will you store it?
What needs to happen in real time?
What can happen later?
How will you process it?
How will someone use the result?
Those questions are the beginning of real Big Data thinking.
Beginner Big Data Projects You Can Try
You do not need petabytes of data to learn Big Data concepts.
That is another misconception worth removing.
A small project can still teach distributed processing, streaming, pipelines, and data architecture.
Project 1: E-Commerce Analytics Pipeline
Goal
Analyze customer orders and identify sales patterns.
Skills
- SQL
- Python
- Data cleaning
- Aggregation
- Visualization
Basic flow
CSV Data
↓
Python Cleaning
↓
Database
↓
SQL Analysis
↓
Dashboard
Questions to answer
- Which products sell most frequently?
- Which categories generate the most revenue?
- Which months show the strongest sales?
- How many customers make repeat purchases?
Project 2: Website Log Analysis
Use a public web-server log dataset.
Investigate:
- Popular pages
- Traffic patterns
- Error responses
- Request frequency
- Unusual activity
Then process the same dataset with a distributed-processing tool.
Now you’re not just analyzing data—you are experimenting with the reason distributed processing exists.
Project 3: Real-Time Event Pipeline
Create a small event generator that produces simulated user activity.
For example:
User opens product page
User adds item to cart
User completes payment
Build:
Event Generator
↓
Kafka
↓
Processing
↓
Storage
↓
Dashboard
The dataset can be small.
The learning objective is understanding the architecture and event flow.
Project 4: Public Transportation Analysis
Use an open dataset containing routes, trips, or passenger activity.
Ask:
- Which routes have the highest activity?
- At what times does demand change?
- Are there noticeable seasonal patterns?
- Which routes have unusual changes?
Then document how you collected, cleaned, processed, and analyzed the data.
That documentation is part of the project—not an optional extra.
Skills That Matter Beyond the Tools
Technology changes.
The underlying skills remain useful.
Problem-Solving
A tool doesn’t tell you what problem deserves attention.
Start with the question.
Then decide what data and architecture are required.
Data Quality
A sophisticated pipeline can still produce poor results if the input data is unreliable.
Learn to recognize:
- Missing values
- Duplicates
- Invalid records
- Inconsistent formats
- Outdated information
System Thinking
Big Data is rarely one isolated program.
Data may travel through several systems before reaching the person or application that needs it.
Understanding the complete flow is valuable.
Communication
A technically correct analysis can still fail if nobody understands what it means.
Practice explaining:
What happened? Why does it matter? What should the reader look at next?
Curiosity
A useful data project often begins with a question:
Why is this happening?
The technical tools help you investigate the answer.
They don’t replace the question.
5 Big Data Misconceptions Beginners Should Avoid
Misconception 1: Big Data Just Means Huge Data
Not necessarily.
Scale matters, but velocity, variety, complexity, and processing requirements matter too.
Misconception 2: You Need Hadoop Before You Can Learn Big Data
No.
Understanding distributed systems is more important than starting with a particular framework.
Hadoop can help you understand the history and concepts of distributed data processing, but it shouldn’t become a barrier to learning.
Misconception 3: Every Big Data Project Needs Billions of Records
No.
A small dataset can still be useful for learning:
- Distributed processing
- Streaming
- Data pipelines
- Architecture
- Fault tolerance concepts
The point of a beginner project is to demonstrate the concept.
Misconception 4: SQL Is Only for Traditional Databases
SQL remains useful across many modern data environments.
Learning it gives you a strong foundation for querying and understanding data.
Misconception 5: More Tools Mean More Skill
Not automatically.
Knowing ten tools superficially is not necessarily more useful than understanding one complete data pipeline from ingestion to analysis.
Depth matters.
Common Beginner Mistakes
Trying to Learn Every Tool
Hadoop, Spark, Kafka, Flink, MongoDB, cloud platforms, warehouses, lakehouses—the ecosystem is large.
Pick a learning path and go deep enough to build something.
Watching Tutorials Without Building
You can watch hours of tutorials and still freeze when faced with an empty project folder.
After learning a concept, use it.
Even a small experiment is better than another hour of passive watching.
Ignoring SQL
Don’t.
SQL gives you a practical way to work with data and remains relevant across many data environments.
Focusing Only on Certifications
Certifications can help validate knowledge, but they aren’t a substitute for practical experience.
A project forces you to solve problems that a test may never present.
Starting With Enterprise-Scale Architecture
You don’t need to design a system for billions of users on your first project.
Start with a small pipeline.
Then ask:
What would break if the data became 100 times larger?
That question is an excellent way to begin thinking like a Big Data engineer.
What Does a Big Data Career Look Like?
Big Data isn’t a single job title.
Depending on your interests, you may encounter roles such as:
- Big Data Engineer
- Data Engineer
- Data Analyst
- Data Scientist
- Cloud Data Engineer
- Analytics Engineer
- Data Architect
- Machine Learning Engineer
These roles overlap, but their day-to-day responsibilities can be quite different.
If you enjoy building pipelines and infrastructure, data engineering may be interesting.
If you enjoy investigating business questions, analytics may be a better area to explore.
If statistics, experimentation, and predictive models interest you, data science may be worth investigating.
If infrastructure and large-scale architecture catch your attention, you may want to explore data platforms and architecture.
You don’t need to decide immediately.
Build some projects first.
Your preferred direction will become easier to recognize once you’ve worked with the technology rather than simply reading about it.
Where Should You Start Today?
If Big Data still feels enormous, make the first step smaller.
Don’t begin with:
“I need to learn Big Data.”
Begin with:
“I need to understand how data moves through a system.”
Then follow a practical sequence:
Data Fundamentals → SQL → Python → Distributed Systems → Spark → Streaming → Cloud → Projects
You can change the order slightly depending on your background.
For example, someone who already knows Python may start with SQL and databases. Someone with a data-engineering background may move into distributed systems sooner.
The important part is the learning loop:
Understand → Build → Break → Fix → Explain
The “break” part matters.
When your pipeline fails, a query returns the wrong result, or your data arrives in an unexpected format, you’re forced to understand what is actually happening.
That is where much of the learning happens.
A Simple 30-Day Starting Plan
If you want a concrete starting point, try this.
Week 1: Data Fundamentals
Learn:
- Databases
- Tables
- Relationships
- SQL basics
- Aggregations
- Joins
Mini task: Analyze a small sales dataset.
Week 2: Python + Data
Learn:
- Python fundamentals
- CSV/JSON files
- Data cleaning
- Basic APIs
Mini task: Write a Python script that cleans and summarizes a dataset.
Week 3: Big Data Concepts
Study:
- Distributed systems
- Nodes
- Clusters
- Partitioning
- Fault tolerance
- Batch vs. streaming
Mini task: Draw your own Big Data architecture for an online store.
Week 4: Build
Choose one:
- E-commerce pipeline
- Log analysis
- Streaming pipeline
- Transportation analysis
Document:
Source → Ingestion → Storage → Processing → Output
By the end of the month, you won’t know everything about Big Data.
That’s fine.
You will, however, have a foundation you can build on.
Final Thoughts
Big Data can look intimidating because the ecosystem is huge.
There are distributed processing engines, databases, streaming platforms, cloud services, warehouses, data lakes, analytics systems, and machine-learning tools.
The mistake is treating that list as a checklist.
You don’t need to collect technologies.
You need to understand problems.
Why can’t one machine handle the workload?
Why does the data need to be processed in real time?
Why is the data being split across systems?
Why does the organization need a particular storage model?
Why does a pipeline need fault tolerance?
Once you start asking those questions, technologies such as Spark, Kafka, Hadoop, SQL databases, NoSQL systems, and cloud services stop looking like unrelated names.
They become pieces of a larger system.
So start with the fundamentals.
Learn SQL. Learn Python. Understand databases. Learn how distributed systems work. Build a small pipeline. Break it. Fix it. Explain what you built.
Then make the next project a little more ambitious.
The goal isn’t to memorize the Big Data ecosystem.
The goal is to understand how large-scale data problems are solved—and become capable of solving some yourself.
That’s how you start Big Data the right way.



No Comments Yet
Be the first to share your thoughts on this post!